Author: Ryan Coleman

96% of IT Leaders Say Their AI Agent Inventory Is Complete. Two in Three Had an Agent Incident Anyway.

Ask most IT leaders whether they know which AI agents are running in their company, and the answer is yes. A new survey suggests that confidence may be running well ahead of the controls behind it. Published by Guild.ai and fielded by Morning Consult, it found that 96.4% of IT decision-makers are confident their agent inventory is complete and accurate, while 66.7% of organizations with agents reported an agent-related operational consequence in the past 12 months.

One point belongs at the top, not the bottom. Guild.ai sells tools for managing AI agents, so this is vendor-sponsored research, and it should be read that way. This piece follows on from our earlier look at shadow AI and sets out what the survey reports, what its wording and bases do and do not support, and what an organization can do with the findings. It is written for teams planning AI governance and AI automation programs for agents, not just buying software for them.

What the survey reports

According to Guild.ai’s September 22, 2026 release, Morning Consult surveyed 362 U.S. IT decision-makers at companies with 100 or more employees. Interviews were conducted online from August 4 to 9, 2026, and the data was weighted by age, company size, industry and role. The margin of error is plus or minus five percentage points for the full survey.

The headline figures are these. 96.4% of IT decision-makers are confident their organization has a “complete and accurate inventory” of its AI agents. 66.7% of organizations with agents had an agent-related operational consequence in the past 12 months. 96% of organizations report agents in production, and 47% of those with agents run dozens or more.

The control figures are lower. 42.7% have a centralized dashboard or monitoring tool, 39.8% have logging or audit trails, and 31% can immediately stop a malfunctioning agent with an automated kill switch. On unapproved use, 60.6% say it is very or somewhat likely that employees deploy agents without formal approval, 35.9% require agents to be registered before deployment, and about half have a formal policy on unauthorized agent use.

Who ran it, and why that matters

Morning Consult fielded the survey, but Guild.ai commissioned and published it. Guild describes its product as a control plane for the agent lifecycle, with offerings that include AI governance and AI observability tools, according to its website. The findings point toward exactly the kind of tooling it sells, such as the 83.9% who rate real-time visibility into agent activity as extremely or very valuable.

That does not make the numbers wrong. Vendor-sponsored surveys can be carefully run, and an outside firm doing the fieldwork counts in its favor. But the sponsor chose which results to feature, so treat the data as informative and the conclusions as the vendor’s.

What the numbers do and do not show

Several details affect how far the headline can be pushed.

The word incident is not defined. The release describes an “agent-related operational consequence” and, elsewhere, an agent-related incident, and neither term is defined in the material we reviewed. A consequence could be a minor disruption or a serious breach. Two in three is a striking figure, but without a definition it does not tell you how serious those events were.

The bases differ. The 96.4% is a share of IT decision-makers. The 66.7% is a share of organizations with agents. The release does not state the base for the monitoring, audit trail and kill switch figures, so they cannot be compared precisely with the others.

The scope may be narrower than it sounds. Guild’s report page describes the survey scope as internally built and actively managed agents. If that is right, the confidence is about agents an organization built and manages, and the survey does not show how confident leaders are about agents employees bring in on their own. The 60.6% on unauthorized deployment is the nearest measure of that, and it is a perception of likelihood, not a count.

Confidence is self-reported. A leader who says the inventory is complete is giving an opinion. The survey did not test whether the inventory was actually complete, so it shows a gap between belief and controls, not a measured gap between the inventory and reality.

The margin of error applies to the full survey. Subgroup figures, such as organizations with agents, rest on fewer respondents and carry more uncertainty than the plus or minus five points suggests.

The confidence gap, read carefully

The core observation is that confidence and controls do not line up. Nearly everyone is confident about the inventory, yet fewer than half have centralized monitoring and fewer than four in ten have audit trails. A complete inventory and no way to see what the agents do is a thin kind of control.

The kill switch figures need a careful reading, because they cut both ways. Only 31% have an automated kill switch. But Guild’s own release reports that 76.5% can stop a malfunctioning agent within minutes, using an automated switch or a manual process. So most organizations say they can stop an agent quickly, and a minority have automation to do it. The accurate summary is that manual shutdown is common and automation is not. Whether a manual process works at three in the morning, or when ten agents misbehave at once, is a different question the survey cannot answer.

A second survey, and the same caveat

A separate survey points in a similar direction. SecureWorld reported on August 31, 2026 on research by Cequence Security and Enterprise Management Associates, which ran the survey for Cequence. It reported that 94% of respondents were at least moderately confident that agents do not have more access than needed, while only 32.7% used least-privilege access scoped to the task. It also reported that 47% could not reliably inventory their agents, and that 65% had seen an agent act outside its intended scope.

The sample was 202 IT and security leaders, and the coverage did not describe fieldwork dates or margins of error. Cequence is also a security vendor. Two vendor-sponsored surveys finding a gap between confidence and practice is suggestive, not conclusive, since both sponsors benefit from that story. A Cequence executive said that confidence “is usually measuring compliance, not cyber”, which is one vendor’s view, not a finding.

Why a confident inventory is not a governed one

An inventory is a list. It tells you which agents exist. AI governance is what you do with the list: who owns each agent, what it may access, who approved it, what it costs, how it is monitored, how its changes are reviewed and how it is stopped or retired.

Seen that way, the survey’s pattern is easy to understand. Teams build agents quickly, record them in a spreadsheet and feel in control. Then an agent changes, a credential is shared or an owner leaves, and the list no longer matches reality. Confidence comes from writing the list. Control comes from keeping it true.

This is also why the registration figure matters. Only 35.9% require agents to be registered before deployment. Without a registration step, an inventory is something someone compiles occasionally, not something the process produces automatically.

What to do with this

You do not need the survey’s sponsor, or any vendor, to act on its lessons. These steps apply whether you buy tooling or do the work by hand.

Test the inventory by evidence. Do not ask whether the list is complete. Look for agents the list does not contain by checking service accounts, API keys, automation platforms and cloud billing for agent activity, and by asking each team what they run.

Assign an owner to every agent. A named person or team should answer for what each agent does and what it can reach.

Make registration a precondition. An agent should not go into production until it is on the list, with its permissions, data access and purpose recorded.

Log actions, not just existence. Keep a record of what each agent did, which tools it called and which data it touched, with enough retention to reconstruct an incident.

Define incident and track it. Agree what counts as an agent-related incident in your organization, from a near miss to a breach, and record each one. You cannot improve a rate you do not measure.

Rehearse the stop. Test how fast you can disable an agent and revoke its credentials, in practice, with the person who would actually do it. If the answer depends on one individual, write it down and share it.

Limit permissions. Give each agent the narrowest access that lets it do the job, and review the access on a schedule.

For businesses planning AI agent development or wider AI automation, these controls are cheaper to design in at the start than to add later. Teams doing generative AI development should treat identity, scoped permissions and logging as part of the build, not as a later compliance task.

Where this leaves you

The confirmed facts are these. Guild.ai published a Morning Consult survey of 362 U.S. IT decision-makers, fielded in August 2026. 96.4% are confident their agent inventory is complete, and 66.7% of organizations with agents reported an agent-related operational consequence in the past 12 months. Fewer than half have centralized monitoring or audit trails. The research is vendor-sponsored, its key terms are not defined in the release, and confidence is self-reported.

The practical response does not depend on any single percentage. Treat a complete-looking list as a starting point: test it, assign owners, log what agents do and practice stopping them, whether you are in AI agent development or simply adopting agents. Organizations that do this can adopt agents faster, because they know what they are running. For anyone building AI development capability, that discipline is the foundation.

Frequently Asked Questions

1. Who ran the Guild.ai AI agent survey?
Guild.ai published it and Morning Consult fielded it. It surveyed 362 U.S. IT decision-makers at companies with 100 or more employees, online, from August 4 to 9, 2026, with a margin of error of plus or minus five points. It is vendor-sponsored research.

2. What are the key findings?
96.4% of IT decision-makers are confident their agent inventory is complete and accurate, and 66.7% of organizations with agents had an agent-related operational consequence in the past 12 months. Only 42.7% have centralized monitoring, 39.8% have audit trails and 31% have an automated kill switch.

3. Does this prove that most companies have a governance problem?
It suggests a gap between confidence and controls, but it does not prove it. Confidence is self-reported, incident is not defined, and the survey is sponsored by a company that sells agent management tools.

4. Is an incident the same as a security breach?
Not necessarily. The release uses the phrase agent-related operational consequence and does not define it, so it could cover anything from minor disruption to serious harm.

5. Can most companies stop a misbehaving agent?
The release reports that 76.5% can stop one within minutes by automated or manual means, but only 31% have an automated kill switch. Manual shutdown may work in a calm test and be harder in a real incident.

6. What is the difference between an agent inventory and AI governance?
An inventory lists which agents exist. Governance covers ownership, permissions, approval, monitoring, change control and shutdown. Strong governance keeps the inventory accurate over time.

7. What should my company do first?
Test your inventory by looking for agents it does not list, then assign an owner to each agent, require registration before deployment and set up logging of what agents do.

If you want to know which of your workflows are ready for AI agents, and where the governance gaps sit, that is exactly what we look at in a free AI Readiness Audit.
Google Switched On Checkout Inside AI Mode for Eligible Shopify Stores. Here Is What It Changes for Your Measurement.

For years, shopping on Google followed a familiar path: a search, a click, a visit to your store, a purchase. Your analytics were built around it. In late September 2026, part of that path moved. Eligible US Shopify merchants can now sell directly inside Google’s AI Mode and the Gemini app, where a shopper taps Buy and pays without ever opening the merchant’s website.

For merchants, the change is both an opportunity and a measurement problem. Sales can arrive from a surface where your tracking does not run. This piece sets out what was announced, who is affected, how to opt out, what the checkout supports and what it does not, and a decision framework for whether to leave it switched on. We have kept to what documentation and reputable reporting confirm, and flagged what is unclear.

What changed

On September 22, 2026, Search Engine Land reported that Google is notifying eligible Shopify merchants that their products can be bought directly in AI Mode in Google Search and in the Gemini app. The checkout runs on the Universal Commerce Protocol, an open standard Google developed with other companies, including Shopify, that lets AI agents interact with merchants and payment systems during shopping.

Two details deserve attention. First, merchants did not have to apply. Search Engine Land reports that eligible products are included automatically once a Shopify store is matched with its Google Merchant Center account, and Shopify’s help center confirms that direct checkout is on by default for eligible stores. Second, the rollout is gradual. Shopify says direct checkout is still rolling out to Google users and may not yet be available in every store, and Google’s own documentation, as quoted by ContentGrip, describes the program as “a phased program for select participating merchants”.

Who is eligible

Shopify’s help center lists the requirements. Your store must be based in the United States and sell to US customers. You need a valid Google Merchant Center account and must meet Google’s requirements, including its free listing eligibility and return policy rules. Your products must be available in Merchant Center, either through Shopify’s Google and YouTube sales channel with product and shipping sync turned on, or through a third-party feed provider or manual upload. Products must also be eligible for Shopify Catalog, you must agree to the Shopify Agentic Storefronts Supplemental Terms of Service, and your terms of service, privacy policy and refund policy must be completed in your Shopify settings.

Direct checkout is shown only to US-based shoppers.

There is no extra fee. Shopify states that you pay only your standard payment processing fees. Merchants also keep the underlying customer and order relationship, according to Search Engine Land, and the retailer remains the seller of record, according to Google’s documentation as cited by ContentGrip.

How to opt out

If you want shoppers to complete purchases on your own site, Shopify’s help center gives these steps. In the Shopify admin, go to Sales channels, then Agentic. Deactivate the setting called Allow Shopify to manage for me. Click Google AI Mode and Gemini. Switch Direct checkout off, then click Save.

Opting out does not remove you from AI Mode. Your products can still appear in results, but shoppers are redirected to your online store to complete the purchase.

What direct checkout supports, and what it does not

The in-AI checkout is not an exact copy of your store’s checkout. Shopify’s documentation sets out the gaps.

Supported: automatic discounts and discount codes, and Shopify Functions for shipping, discounts and cart and checkout validation.

Not supported: subscriptions, product bundles, customizable products and B2B-only products. Local delivery, in-store pickup and pickup points. Requiring customers to sign in before checkout. Only a subset of accelerated checkout options. Many checkout blocks, including upsells, loyalty and rewards blocks, consent collection blocks, chat blocks and trust badges, may not display, so the checkout can look different from your own. Shopify also asks that required legal disclosures appear within the first 6,000 characters of a product description.

Why this is a measurement problem

Shopify’s help page states plainly that “Google Analytics and custom pixels won’t fire” in direct checkout. Only server-to-server pixel events fire, and only two of them: checkout started and checkout completed.

Your analytics tag, ad platform pixels and attribution tools all depend on code running in the shopper’s browser on your site. When the purchase happens inside Google’s surface, that code never loads. The sale is real, but the session your tools normally record does not exist on your side.

Three practical consequences follow.

Revenue can be undercounted in tools that rely on client-side tracking. If you compare Google Analytics revenue with Shopify order totals, a widening gap may be this checkout, not a tracking bug.

Channel reporting can shift. Because the journey no longer includes a visit to your site, orders may not be credited the way you expect. Shopify’s page does not describe how these orders are labeled in your admin or reports, and we found no authoritative source that does, so treat any confident claim about it with caution.

Funnel analysis loses steps. These buyers generate no product page views, add-to-cart events or checkout steps on your site, so a shift in conversion rate could reflect where people buy, not how well your pages convert.

The practical answer is to reconcile against Shopify’s own order data, which records the purchase wherever it happens, and to stop treating the browser-side analytics tag as the only source of truth for revenue.

What is still unclear

Some claims in circulation should stay out of your planning until they are confirmed. Some coverage repeats specific review thresholds, such as a minimum number of reviews and a minimum star rating. Those figures relate to Merchant Center’s store ratings rules for showing ratings with ads, and we could not confirm that they are conditions for this checkout. Shopify’s eligibility list above does not include them.

Reports of a separate, wider default-on rollout of agent checkout across Shopify, including a figure of about one million merchants, rest on thin sourcing, so we have not relied on them.

Finally, there are open questions on reporting: how these orders are labeled, what Google will offer in Merchant Center for AI surface performance, and how consent settings apply. Recheck the documentation before committing.

Opt in or opt out: a decision framework

There is no single right answer. It depends on what you sell and how you measure it. Use these questions.

Do you sell subscriptions, bundles, customizable items or B2B-only products? If these make up a large share of revenue, the AI checkout cannot handle them, and keeping the feature on mainly matters for your simpler products.

How much of your profit comes from checkout upsells or loyalty features? If the answer is a lot, redirecting shoppers to your own checkout protects that revenue.

How dependent is your reporting on client-side tracking? If your team, or your agency, cannot trust revenue numbers without it, you may prefer to opt out until your reporting is ready.

Do you want to learn? Some merchants will reasonably leave it on for a few weeks and compare Shopify order data with previous periods, as long as they set a review date.

For most stores, a good default is to keep the feature on for a defined trial period if your product mix is mostly simple, one-time purchases, and to switch it off if subscriptions, bundles or upsells drive revenue.

What to do this week

Open the Agentic section in Shopify and see whether direct checkout is on for your store.

Review your Merchant Center feed and your Shopify policies. Product discovery in AI Mode is powered by Merchant Center, so missing attributes, mismatched prices or incomplete return policies can limit what shows up.

Check product descriptions for legal disclosures in the first 6,000 characters.

Place a test order if possible and see how it appears in Shopify and in your analytics.

Reconcile weekly. Compare Shopify order totals with analytics revenue.

Why this matters for visibility

This checkout sits at the end of a discovery path, and the path begins with product data. Shopify’s documentation says product discovery in AI Mode is powered by Google Merchant Center, so a store whose data is complete and consistent has a better chance of being shown. That is where search engine optimization, generative engine optimization and answer engine optimization meet ecommerce: accurate titles, complete attributes, clear policies, authentic reviews and consistent information across your site and your feed.

The checkout does not change the basics. It raises the stakes on them, because a recommendation in an AI answer can now turn into a sale without a visit to your site. For brands that want to understand how they appear in these answers before deciding how to respond, an AI Visibility Audit is a sensible starting point, because you cannot manage what you have not measured.

Where this leaves you

The confirmed facts are these. Google and Shopify have enabled a native checkout in AI Mode and the Gemini app for eligible US Shopify merchants, powered by the Universal Commerce Protocol. It is on by default for eligible stores and can be turned off in the Agentic settings. Merchants keep the customer and order relationship. Google Analytics and custom pixels do not fire, and only server-to-server started and completed events are sent. Several features, including subscriptions and bundles, are unsupported.

The response is a decision, not a panic. Check your setting, choose deliberately, protect what depends on your own checkout, and measure through Shopify’s order data while your reporting catches up. Strong search engine optimization, generative engine optimization and answer engine optimization all start with clean product data, either way.

Frequently Asked Questions

1. Is Google’s AI Mode checkout turned on for my Shopify store?
If your store is based in the US, sells to US customers and is matched with a valid Merchant Center account, it is likely eligible, and Shopify says direct checkout is on by default for eligible stores. The rollout is gradual, so check Sales channels, then Agentic, in your Shopify admin.

2. How do I opt out of direct checkout in AI Mode?
In Shopify admin, go to Sales channels, then Agentic. Deactivate Allow Shopify to manage for me, click Google AI Mode and Gemini, switch Direct checkout off and save. Your products can still appear, but shoppers are sent to your online store to buy.

3. Do I still own the customer and the order?
Search Engine Land reports that merchants keep the underlying customer and order relationship, and Google’s documentation, as cited by ContentGrip, says the retailer remains the seller of record. Shopify charges no extra fee beyond standard payment processing.

4. Will Google Analytics track these purchases?
No. Shopify’s help page says Google Analytics and custom pixels do not fire in direct checkout. Only server-to-server started and completed events are sent. Use Shopify’s order data to reconcile revenue.

5. Which products and features does the AI checkout not support?
Subscriptions, bundles, customizable products and B2B-only products are not supported, nor are local delivery, pickup or required sign-in. Many checkout blocks, such as upsells, loyalty and consent blocks, may not display.

6. Do I need 100 reviews and a 3.5 star rating?
We could not confirm that. Those figures relate to Merchant Center store ratings for ads and are not on Shopify’s eligibility list.

7. Should I leave it on or switch it off?
It depends on your product mix and your reporting. Stores with mostly simple, one-time purchases may reasonably test it for a defined period. Stores that rely on subscriptions, bundles, upsells or client-side tracking may prefer to opt out.

If you want to know how your brand and products show up across Google and AI answer engines, that is exactly what we look at in a free AI Visibility Audit.

Salesforce Just Gave Its AI Agents Names, Job Titles and Goals That Run for Weeks

For the last two years, enterprise AI has mostly been sold as a feature: a chatbot in the corner of a screen, a summarize button, an assistant that answers one question at a time. On September 11, 2026, Salesforce made a different kind of pitch. It introduced seven named Agentforce agents, each built for a specific job, and described one of them as able to pursue a goal across weeks instead of a single conversation.

The naming is not a cosmetic detail. It signals a shift in how vendors want buyers to think about AI: less as software you configure and more as labour you deploy. This piece follows on from our earlier look at MCP and A2A governance, and it covers what Salesforce announced, what its customer results do and do not show, and what a buyer should ask before treating an AI agent like an employee.

What Salesforce announced

According to Salesforce’s announcement and coverage from Unite.AI and Startup Fortune, the seven agents and their jobs are as follows.

Casey is a help agent for customer service, working across voice, SMS, WhatsApp, and web chat. Paige handles IT and HR requests for employees, including through Slack and employee portals. Carter is a shopper agent that helps with product discovery, comparison, and checkout. Marshall is a supply chain agent that orchestrates back-office processes with audit trails. Piper handles inbound lead generation, engaging and qualifying leads for B2B sales. Fin is a customer agent that resolves complex customer-experience workflows. Hunter is an outbound sales agent that manages a pipeline from research through outreach.

Availability differs. Six of the seven, Casey, Paige, Carter, Marshall, Piper, and Fin, are generally available now. Hunter is in pilot, with general availability planned for November 2026.

Hunter is also the agent that uses a new long-horizon runtime. Salesforce describes it as built on three capabilities: memory, which preserves context across sessions; durable execution, which keeps a plan running over time; and dynamic steering, which adapts behavior based on feedback from users. The point of the runtime is that an agent can work toward a goal across days and weeks, instead of finishing one task and forgetting it. Hunter is the first agent to run on it.

The announcement included other platform pieces. Multi-Agent Orchestration, which routes work across coordinated teams of agents, is generally available. Agentforce Coworker, an employee-facing agent with AI Skills, and Agent Optimizer, a tool for refining agents, are scheduled for general availability in October 2026. Salesforce also introduced Agent Script, an open-source language for defining agent behavior with deterministic rules, which matters because it gives builders a way to fix certain steps in place instead of leaving everything to the model. None of the coverage we reviewed gave pricing.

How long the memory lasts

Some headlines around this launch describe agents with months of memory. The sources we reviewed do not support that. Salesforce’s own description is days and weeks. That is still a meaningful change, but the difference matters when a buyer is estimating how long an agent can hold onto a plan.

The customer results, and why to read them carefully

Salesforce published six customer results with the launch. All of them are reported by Salesforce, and none of the coverage we reviewed included independent verification or a definition of how each metric was measured.

Engine reported that 50% of chat inquiries are fully resolved by its help agent, which it calls Eva. Perk reported that Hunter built 60% of its sales pipeline. Autism Queensland reported that Paige resolves 70% of administrative requests. Hibbett reported that an agent handles 90% of core shopper journeys, after going live in six weeks. Asana reported 4x conversation volume driven by Piper. Anthropic reported that Fin resolves 79% of conversations autonomously.

These are useful as directional evidence. They are not benchmarks, and four things are missing that any buyer should ask about.

The first is definitions. Resolved could mean that a customer got a correct answer, or it could mean that the conversation ended without escalation. Those are very different outcomes. The second is baselines. Fifty percent resolved means more or less depending on what was resolved before the agent arrived. The third is scope. A figure for one team, one region, or one channel may not transfer to your business. The fourth is selection. Vendors highlight their strongest results, so a set of six published numbers says little about the distribution of outcomes across all customers.

There is one specific point on Perk. Hunter is still in pilot, so that result necessarily comes from early use, not a generally available product. Startup Fortune’s coverage made the same overall point, describing the results as early evidence and not a guarantee.

The governance layer was announced separately

Coverage of this launch sometimes lumps the AI Control Plane in with the seven agents. It was announced separately, one day earlier, on September 10, alongside what Salesforce calls a Trusted Enterprise AI Harness.

According to AI Weekly, the control plane provides routing, lineage, and cost and observability across both Salesforce and third-party AI, and it is positioned as a governance layer over a multi-vendor agent landscape. An analyst blog covering Dreamforce described it as a central registry of agents, MCP servers, and APIs with automatic discovery and a single gateway for model, MCP, and agent calls, and said it is designed to cover agents beyond Salesforce’s own.

Two cautions apply. AI Weekly reported that most capabilities are live while the rest are scheduled for fiscal year 2028, so buyers should not assume everything described is available today. And the same analyst blog noted that the control plane was initially previewed in 2025, which suggests some of it is an evolution of earlier work and not new this month. Neither source gave a general availability date for the full set.

A registry of agents, MCP servers, and APIs is exactly the kind of inventory that AI governance requires. It is also a reminder that governance products from a platform vendor cover that vendor’s view of the world first, so a company running agents from several suppliers should test how well the third-party coverage actually works.

Why names and job titles matter

Giving an agent a name and a role is a marketing decision, and it is also a framing decision. A named agent with a job title invites the same expectations we place on a person in that role: that it owns an outcome, that someone is accountable for it, and that it can be evaluated like a hire.

That framing has real benefits. It gives buyers a clearer mental model than a generic assistant. It pushes vendors to tie agents to measurable jobs such as resolving support tickets or qualifying leads, which is what sensible AI automation projects do anyway. And it makes it easier for a business to ask what work is being replaced, augmented, or created.

It also creates a risk. Names encourage people to trust an agent in the way they would trust a colleague, and an agent is not a colleague. It has no professional judgment, no personal accountability, and no understanding of context beyond what it has been given. Startup Fortune raised the question directly: “which decisions stay with people, which ones the agent takes alone?” That question should be answered in writing before an agent goes live, not discovered after an error.

Why weeks-long agents change the risk

The long-horizon runtime deserves separate attention, because it changes what can go wrong. A chatbot that answers one question and forgets it produces contained errors. An agent that holds a plan for weeks, remembers past interactions, and adjusts its behavior can compound a mistake, act on stale information, or continue a course of action after circumstances have changed.

Memory also raises data questions. What does the agent retain, for how long, and who can see or delete it? Durable execution raises control questions. How do you pause or stop an agent that is mid-plan, and how do you review what it did while nobody was watching? Dynamic steering raises accountability questions. When feedback changes an agent’s behavior, who approved that change?

These are design questions for anyone working on AI agent development, and they are procurement questions for anyone buying agents. The sensible default for a weeks-long agent is tighter limits: narrow permissions, explicit approval for irreversible actions, clear stop conditions, and a complete log of what it decided and why.

What to ask before you deploy a job-ready agent

Whether you buy from Salesforce or another vendor, the same questions apply.

What exactly is the job, and how is success measured? Define the metric before the pilot, including what counts as resolved or qualified.

What does the agent decide alone, and what needs a person? Write the boundary down and test it.

What data does it read, retain, and write? Confirm retention periods and deletion.

How do you audit and stop it? This is the core of AI governance for agents. Ask to see the logs and the pause controls.

How does it behave when it is wrong? Test escalation paths and error handling with real edge cases.

What is the fallback? Keep a documented way to run the process without the agent.

How does it fit with the rest of your agents? If you run agents from more than one vendor, check whether the governance layer really covers them.

Where this leaves you

The confirmed facts are these. Salesforce launched seven named agents on September 11, 2026. Six are generally available and Hunter is in pilot until a planned November release. Hunter runs on a new runtime designed to pursue goals over days and weeks. A separate governance announcement the day before introduced an AI Control Plane, with parts still to roll out. All customer results are Salesforce-reported and lack published definitions.

The broader shift is real. Enterprise AI is increasingly sold as a defined piece of work with a name attached. That makes it easier to evaluate, provided you insist on definitions, baselines, and limits. Businesses exploring AI automation, AI agent development, or generative AI development can borrow the useful part of the framing, which is to scope each agent to a specific job, and skip the risky part, which is treating it like a person.

Frequently Asked Questions

1. What are the seven Agentforce agents?
Answer: Casey (customer service), Paige (IT and HR), Carter (shopping), Marshall (supply chain), Piper (inbound lead generation), Fin (customer experience workflows), and Hunter (outbound sales). Salesforce announced them on September 11, 2026.

2. Which agents are available now?
Answer: Casey, Paige, Carter, Marshall, Piper, and Fin are generally available. Hunter is in pilot, with general availability planned for November 2026.

3. What is the long-horizon runtime?
Answer: It is a new runtime that lets an agent pursue goals across days and weeks using memory, durable execution, and dynamic steering. Hunter is the first agent to use it.

4. Are Salesforce’s customer results independent?
Answer: No. All six results are reported by Salesforce, and the coverage reviewed did not define how metrics such as resolved were measured. Treat them as directional evidence, not benchmarks.

5. What is the AI Control Plane?
Answer: It is a governance layer announced separately on September 10, 2026 that provides routing, lineage, cost and observability across Salesforce and third-party AI. Some capabilities are live and the rest are scheduled for fiscal year 2028.

6. How should a business evaluate an AI agent before deploying it?
Answer: Define the job and success metric, set the boundary between agent and human decisions, confirm data retention, check audit logs and stop controls, and test failure handling.

If you want to know which of your workflows are ready for AI agents and where the risks sit, that is exactly what we look at in a free AI Readiness Audit.

Google Is Now Hiding the Real Links in Its Search Results, and What It Breaks, and What It Doesn’t

On August 26, a Google spokesperson confirmed what SEOs had already been spotting in the wild since late June. Search result links are being rewritten to route through google.com/goto before landing on the actual destination page. Google’s stated reason was procedural: it said it regularly deploys technical measures to protect its services and users from evolving abuse. This sits alongside a separate legal fight, Google’s suit against SerpAPI, first filed in July and amended in August, over how that company accesses Google’s search results.

That much is confirmed. What happens after that point, in coverage of this story, splits into two very different camps, and it is worth being precise about which claims are actually settled and which ones are not before you act on either.

What actually changed, mechanically

Instead of a result linking straight to a destination page, the link now points to google.com/goto, with the destination URL encoded using Protocol Buffers, Google’s own binary data format. A server-side redirect on Google’s end then forwards the visitor to the real page. For a person clicking a result, nothing looks different. They click, they land where they expected. What changed sits entirely underneath that click, in a URL structure that any tool reading destination links now has to parse differently than before.

Third-party tools that read destination URLs directly took the first hit, and here the evidence is solid because the vendors themselves reported it. SerpAPI confirmed impact across several of its products. Ahrefs confirmed what it called a temporary inconsistency in its data. One rank-tracking vendor documented a real six-day window, August 26 through September 2, where its Share of Voice reporting misattributed clicks because its parser was not reading the new format correctly. That has since been fixed, with the affected data being backfilled for customers.

Not every tool broke the same way, and this is worth sitting with for a moment. SE Ranking and Semrush both confirmed no impact on their own position tracking data at all. So the blanket claim that the /goto redirect broke SEO tools is not quite accurate. Some tools broke. Others, reading the exact same search results pages, did not, which suggests the difference has more to do with how each vendor’s parser was originally built than with the redirect itself being universally disruptive.

Where the coverage actually splits

Here is where a real divide appears. Several sources treat GA4 organic-to-direct misattribution as an established, active problem, describing what one piece called “massive organic attribution data loss” and sudden, unexplained spikes in Direct traffic. That framing has spread fast, because it is the scariest possible read of a genuinely technical, genuinely unresolved situation, and alarming framing tends to travel faster online than careful, hedged framing ever does.

Now look at what the more carefully sourced coverage actually says. As of late August, one detailed technical write-up stated plainly that nobody had reported confirmed organic undercounting inside GA4. A separate analysis went further and ran an actual test across ten device and browser combinations, checking whether referrer data survived the redirect chain. It found the referrer stayed intact in every case, and GA4 correctly classified those sessions as Organic Search each time. Multiple outlets, working independently of each other, land on the same conclusion. Google has not confirmed a GA4 attribution impact, and the direct evidence gathered so far does not show one either.

None of that means the concern is baseless. The mechanism Google’s own documentation describes makes an attribution gap plausible in principle. If a redirect chain ever strips referrer data before it reaches your site, GA4’s fallback logic would file that session as Direct rather than Organic Search, silently, with no alert generated anywhere in your dashboard. That is a real risk worth watching closely. It is not the same thing as a confirmed, ongoing problem, and treating it as something that has already happened is exactly the kind of overstatement that risks needing a correction once more data actually comes in, one way or the other.

Why the distinction actually matters

It would be easy to read the last two sections and conclude the difference between disputed and confirmed is mostly semantic. It is not, and the practical stakes are worth spelling out.

If a team reacts to this as a confirmed GA4 problem, the natural response is to start second-guessing every organic traffic number reported for the past month, which burns real time reconciling data against a theory that current testing does not support. Budget conversations get harder to have with confidence when the underlying numbers are being treated as suspect without evidence. Reporting to a client or a leadership team gets shakier too, since telling a room that your organic numbers might be wrong because of a redirect Google has not confirmed affects attribution is not a comfortable thing to say out loud in a review meeting.

If a team instead treats this as a plausible, unconfirmed risk worth monitoring, the response looks completely different. You set a baseline, you watch two specific ratios over the following weeks, and you keep operating normally in the meantime rather than freezing decisions around a risk that has not actually materialized in the testing done so far. That is the more defensible position given what is currently known, and it is also simply less exhausting to maintain.

A second, less-discussed layer

There is a second angle here that is easy to miss if you are only thinking about traditional search engine optimization reporting. Reports say /goto-wrapped URLs are starting to show up as cited sources inside ChatGPT, Perplexity, and Claude, wherever those systems pull from Google’s search results as part of answering a query. If a citation-tracking tool has the same blind spot rank trackers had in late August, before their parsers caught up, the same kind of silent misattribution could in theory apply to AI citation counts, not only to GA4 sessions.

Nobody has published confirmed data on this specifically yet either. It follows the same underlying mechanism, and the same caution about calling something confirmed before the evidence is actually in applies here just as much. This is precisely the kind of gap that generative engine optimization and answer engine optimization work now has to account for. Visibility inside an AI answer is only useful if you can actually measure it, and a measurement tool with an unpatched blind spot will quietly undercount exposure it should be reporting, in exactly the way several rank trackers briefly did in late August.

Setting a baseline instead of guessing

The sensible response to a disputed, plausible-but-unconfirmed risk is not to panic and it is not to ignore it. It is to set a baseline now, so that if this ever does show up in your own data, you catch it immediately instead of noticing it months later as an unexplained trend with no starting point to compare against.

Record this week’s ratio of Search Console clicks to GA4 organic sessions for your key properties, and write the number down somewhere you will actually revisit. Do the same for your current organic-to-direct traffic split. These two figures are your tripwire. If either one moves meaningfully in the weeks ahead with nothing else in your setup changing, that is your signal to look closer, rather than reacting to someone else’s alarmed blog post as though it were your own data.

Reconcile Search Console against GA4 weekly for the next month, instead of your usual monthly cadence. A real attribution gap, if one exists, would show up as a widening divergence between the two figures over time, not as a single dramatic jump you would notice immediately anyway.

Check your GA4 referral exclusion list for any new entries appearing as google.com/goto. If Google’s own redirect domain starts showing up there as a distinct referral source, rather than resolving cleanly through to Organic Search, add it to your exclusions so it does not fragment your organic channel into two separate, harder-to-reconcile pieces.

Hold off on reacting to a rank-tracker alert this week unless you have confirmed that specific tool already adjusted its parser to read the new /goto format correctly. Given that SE Ranking and Semrush reported no impact while SerpAPI and Ahrefs did, an alert from a tool that has not caught up yet is more likely a parsing problem on their end than an actual ranking change on your site.

And if you are already doing any AI visibility tracking, apply the same caution to what you see there. A cited source appearing as a raw /goto link rather than a resolved domain in your reporting is a sign your tool needs to catch up, not evidence that your underlying citation count has actually changed.

Where this leaves you

Google confirmed the redirect itself on August 26. It has not been confirmed, and the direct testing done so far does not support a GA4 attribution problem. Some SEO tools broke, others did not, and the ones that did have mostly already fixed their parsers by now. The plausible risk to your own analytics is real enough to baseline and monitor closely. It is not, as of this writing, a confirmed, active problem serious enough to justify the level of alarm some coverage is giving it, and treating an unconfirmed risk as settled fact is its own kind of mistake, one that tends to send teams chasing a problem that is not actually there yet while a genuinely useful baselining exercise gets skipped entirely.

Frequently Asked Questions

1. Is Google’s /goto redirect confirmed?
Answer: Yes. A Google spokesperson confirmed the rollout on August 26 and described it as a technical measure to protect Google’s services and users from evolving abuse. The rollout itself is not in dispute anywhere in the coverage. What remains unsettled is how far its effects reach.

2. Is my GA4 organic traffic being misattributed because of it?
Answer: Not as far as anyone has confirmed. Google has not acknowledged a GA4 attribution impact, and one technical test across ten device and browser combinations found referrer data stayed intact, with sessions classified as Organic Search. The risk is plausible in principle, so it is worth monitoring, but it is not a confirmed problem.

3. Why is my rank tracker showing odd data?
Answer: It depends on the tool. SerpAPI and Ahrefs confirmed some impact, with Ahrefs calling it a temporary inconsistency, while SE Ranking and Semrush confirmed none. Check whether your vendor has published a statement or a fix before assuming your rankings actually moved.

4. Does this affect AI citation tracking?
Answer: Possibly, but nothing is confirmed. /goto-wrapped links are reportedly appearing as cited sources in ChatGPT, Perplexity, and Claude. A tool that cannot parse them could undercount your citations. Treat any sudden citation drop as a possible tracking issue first, and verify it manually.

5. What should I check first?
Answer: Record this week’s ratio of Search Console clicks to GA4 organic sessions, plus your organic-to-direct traffic split. These two numbers are your baseline. If either shifts meaningfully with nothing else changing, investigate then.

6. How often should I reconcile Search Console and GA4?
Answer: Weekly for the next month, instead of monthly. A genuine attribution gap would show up as a widening divergence between the two over several weeks, not as a single sudden jump.

7. Should I change my SEO strategy because of this?
Answer: No. Nothing about the redirect changes how rankings are earned. Keep your strategy as it is, baseline your data, and update only if a confirmed impact emerges.

If you want a second set of eyes on whether your own reporting, or your AI visibility specifically, is being affected, that is exactly what we check in a free AI Visibility Audit.

AI Agents Just Got a Shared Governance Standard. Most Companies Still Can’t Get One Into Production.

On 17 August, Google’s A2A protocol became a hosted project of the Agentic AI Foundation at the Linux Foundation, the same neutral body that already stewards Anthropic’s MCP. Axios broke the story first, and coverage followed within two days across the AI trade press. Nothing about the technology changed. No specification was rewritten and no API broke. What changed is who is responsible for where these standards go next, and that answers a genuine, practical fear for anyone buying agent technology right now: whether committing to one vendor’s agents locks you out of everyone else’s.

At the same time, the agentic AI adoption numbers tell a very different story from the governance news. Most enterprises still cannot get an agent past a pilot. Both things are true at once, and understanding why matters more than either headline on its own.

What actually changed on 17 August

Two protocols now sit under the same governance roof at the Agentic AI Foundation, AAIF for short.

MCP, the Model Context Protocol, was Anthropic’s founding contribution to AAIF when the foundation launched on 9 December 2025. MCP defines how a single AI agent connects to tools, data and applications, essentially the wiring between an agent and everything it needs to actually do work.

A2A, the Agent to Agent protocol, is what Google built to solve a different problem, how independent agents built by different vendors discover each other, hand off tasks and coordinate across organisational boundaries. Google had already donated A2A to the Linux Foundation back in June 2025. What happened on 17 August was narrower and more specific, A2A moved from the Linux Foundation’s general portfolio into AAIF specifically, the foundation built for agentic AI, joining MCP under one roof.

It is worth being precise about what this was not. Coverage of the move has been careful to point out that this is not an ownership event. Each protocol keeps its own maintainers, its own specification process and its own release schedule. What the foundation actually settled is who stewards the specifications going forward, not who controls them technically. What it left unsettled is arguably more important for a business evaluating this, which agent gets to read which data when multiple vendors are involved. Shared governance answers the communication question. It does not answer the access and responsibility question, and that gap is still something every enterprise has to work out contractually, not technically.

AAIF has grown fast since December, from under 40 member organisations to more than 250. The platinum members list reads like most of the industry that matters here, AWS, Anthropic, Block, Bloomberg, Cloudflare, Google, Microsoft and OpenAI all sit on it together, which is notable given how rarely these companies share governance of anything.

Google Cloud’s VP for agent infrastructure, Rao Surapaneni, explained the practical reasoning to Axios plainly. Enterprises are deploying agentic systems from multiple technology providers, and those agents need to actually work together. A protocol that only one vendor controls does not solve that problem. A protocol under neutral, shared governance at least has a chance to.

Why this is a bigger deal than it sounds

If you are not building agent infrastructure yourself, a protocol governance change can sound like plumbing news, and mostly it is. But the practical question underneath it is one every business evaluating AI agent vendors right now should be asking.

Before this kind of consolidation, building a multi-agent system meant either committing to one vendor’s full stack, or writing custom integration code for every agent-to-agent handoff yourself. Neither is a comfortable position. The first creates lock-in. The second creates a maintenance burden that grows with every new agent you add.

With MCP and A2A both governed by the same neutral body, the practical effect is that agents built on different platforms have a real, shared standard for talking to each other, rather than a patchwork of vendor specific bridges that break every time one side updates. That does not eliminate vendor lock-in entirely, plenty of it can still happen at the platform layer above these protocols, but it meaningfully lowers the risk of choosing a vendor today and finding yourself boxed in a year from now.

This is not purely theoretical. A2A has already moved past the pilot stage in its first year, with reported adoption spanning supply chain, financial services, insurance and IT operations, sectors where coordinating autonomous systems across multiple tools, vendors and environments is not optional, it is the whole point. Those are also, not coincidentally, some of the same sectors leading on actual production use of agents generally, which suggests the businesses that need multi-vendor coordination most are the ones pushing hardest for exactly this kind of shared standard.

For a business evaluating who to build an AI agent strategy with, this is now a fair question to ask any vendor directly: do your agents speak MCP and A2A, or only your own proprietary protocol.

The number that matters more than the governance news

Here is the part most coverage of this story skipped entirely, and it is the more important half.

Gartner’s most recent enterprise survey found that 80 percent of enterprise applications shipped or updated in the first quarter of 2026 now embed at least one AI agent, up from just 33 percent two years earlier. The range is wide, everything from a customer service deflection bot handling routine queries to a fully autonomous coding agent opening pull requests against a shared repository. That sounds like near universal adoption, and by one measure, it is.

Separate research from S&P Global Market Intelligence and McKinsey tells a different part of the story. Only 31 percent of enterprises actually have an agent in production. Adoption and production are not the same thing, and the gap between them is enormous. Banking and insurance lead at roughly 47 percent in production. Healthcare sits at 18 percent, government at 14 percent.

A separate KPMG survey from earlier this year adds another layer to the same picture. 42 percent of US enterprises have tested or deployed AI agents in some form, but only 15 percent have actually achieved scaled, orchestrated multi-agent adoption, meaning multiple agents working together rather than one isolated tool running in one workflow. Most organisations that have started are still stuck well short of the coordinated setup that actually needs a protocol like A2A in the first place.

Research from MIT’s NANDA initiative puts a number on exactly where projects stall. Of custom enterprise AI tools built, roughly 60 percent get evaluated, about 20 percent make it to a pilot, and only 1 in 20, five percent, actually reach production. The drop happens overwhelmingly between pilot and production, not between idea and pilot. Getting something working in a demo has never been the hard part.

Gartner’s own forecast is blunter still, more than 40 percent of agentic AI projects are expected to be cancelled before the end of 2027, cited reasons being escalating costs, unclear business value and inadequate risk controls.

A governance standard for how agents talk to each other does not fix any of that. AI agent interoperability was never the reason most agent projects stall between pilot and production. The reasons are the same ones we wrote about a fortnight ago covering AI readiness generally, the wrong use case gets chosen, the data underneath the agent was never actually ready, nobody owns the system once it is live, and success was never clearly defined before the build started. A protocol under good governance still fails against a process that never met those four conditions to begin with.

What this actually means if you are building an agent strategy

Two separate decisions are getting easier to make right now, and it is worth treating them as separate, because conflating them is exactly how a business ends up with a technically sound agent that never earns its keep.

Which protocol standard to build on just got clearer. MCP and A2A, under shared neutral governance with the backing of every major cloud and AI lab, are a safer long term bet than a vendor’s proprietary alternative. Ask any agent vendor directly whether they support both, and treat a vague answer as a warning sign rather than a technicality to sort out later.

Whether your business is actually ready to run an agent in production has nothing to do with this news at all. That question is still answered the same way it always was, by checking whether the process you want to automate is repeatable, runs at real volume, follows consistent rules, and is expensive enough in hours that solving it is worth the build. A governance standard makes the plumbing safer. It does not make a badly scoped project succeed, and it will not move you from the 69 percent still stuck outside production into the 31 percent who have actually gotten there.

The businesses currently sitting in that 31 percent did not get there because they picked the right protocol first. They got there because they picked the right process first, and only then worried about the technical layer underneath it.

Frequently asked questions

1. Did the protocol itself change on 17 August?
Answer: No. No specification was rewritten and no API changed for existing users of either MCP or A2A. What changed is which body stewards A2A going forward, moving it into the Linux Foundation’s Agentic AI Foundation alongside MCP rather than sitting in the Foundation’s broader, less specialised portfolio.

2. What is the actual difference between MCP and A2A?
Answer: MCP connects a single AI agent to the tools, data and applications it needs to do its job, essentially agent to tool. A2A connects independent agents to each other, so agents built by different vendors or teams can discover one another and hand off work, essentially agent to agent. They solve different layers of the same overall problem.

3. Does this mean vendor lock-in with AI agents is solved?
Answer: No, and no announcement has claimed that. Lock-in can still happen at the platform layer above these protocols through proprietary extensions or platform specific features. What has improved is the baseline, the core communication layer is now under shared governance rather than controlled by any single company. Data access and responsibility between agents from different vendors is still something you need to settle contractually, governance of the protocol does not settle it for you.

4. Why do 80 percent of companies have agents but only 31 percent have them in production?
Answer: The two figures measure different things. Having at least one agent embedded somewhere in an application is a low bar that most enterprises have now cleared. Running an agent reliably in production, with proper monitoring, ownership and a clear success measure, is a much higher bar, and most organisations have not built the operating discipline for it yet. Separate research puts the actual production rate for custom built tools as low as 5 percent, with most of the drop-off happening between pilot and production specifically.

5. Which industries are actually using this in production already?
Answer: Banking and insurance lead general agent production use at around 47 percent. On the interoperability side specifically, A2A’s first year of adoption has concentrated in supply chain, financial services, insurance and IT operations, sectors where coordinating agents across multiple vendors and systems is a core requirement rather than a nice to have.

6. Should this change which AI agent vendor we choose?
Answer: It is worth adding as one factor. Ask whether a vendor’s agents support MCP and A2A as open standards, since that reduces your long term switching cost. It should not be the only factor. Whether the vendor can actually help you scope a use case that clears the readiness bar matters more than protocol support alone.

If you are trying to work out whether a specific process in your business is actually ready for an AI agent, or whether the agent conversation you are having is solving the wrong problem entirely, that is exactly what we walk through in a free AI Readiness Audit.

AI Marketing Tools: A Practical Framework for Choosing and Actually Using Them

See also our related guide: AI Integration Services: The Complete Guide.

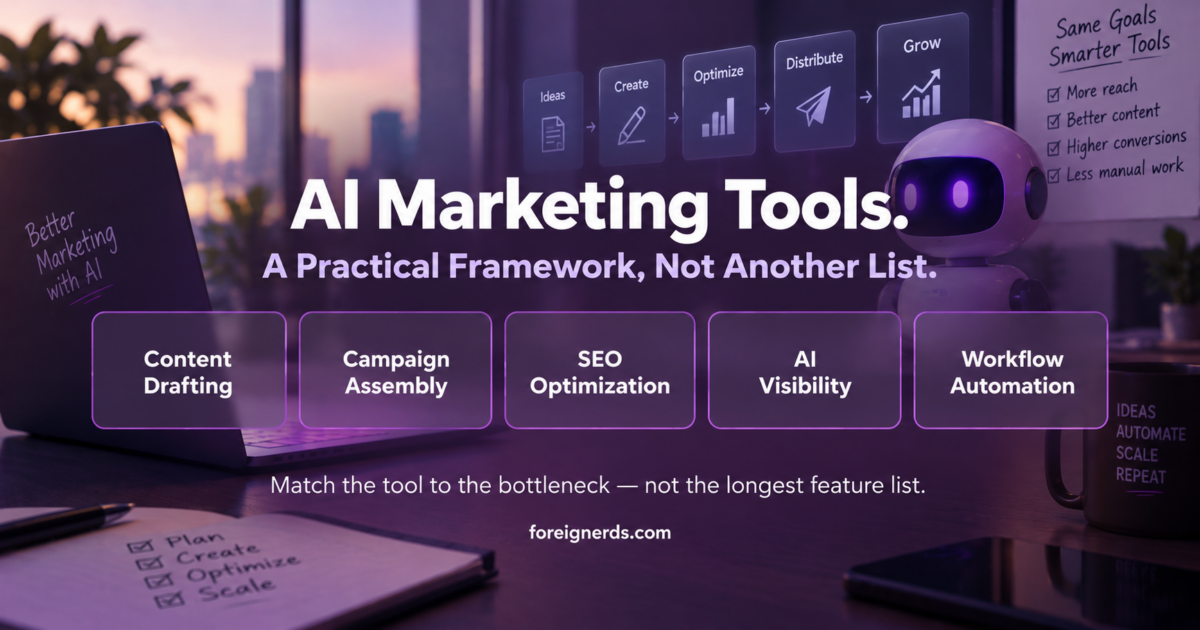
AI marketing tools framework: content drafting, campaign assembly, SEO optimization, AI visibility, workflow automation

AI marketing tools are software products that use machine learning to automate marketing tasks — writing copy, analyzing audience data, optimizing ad spend, and generating creative assets — rather than doing them manually. Dozens of new tools launch every month, and by mid-2026 most marketing teams use at least five of them without a coordinated strategy connecting them.

The Problem With Every “Best AI Marketing Tools” List You’ve Already Read

Search for this exact topic and you’ll find the same article eight different ways: a numbered list of 17, 25, 30, or 36 tools, usually grouped by category, usually including the same five or six names — ChatGPT, Jasper, Canva, HubSpot’s Campaign Assistant, Surfer SEO. Every one of these lists is accurate. None of them answer the question that actually matters once you’ve read the list: which of these should your specific business actually use, in what order, and how do they work together instead of creating five disconnected subscriptions nobody remembers to check?

That’s the real gap. A list of tools is not a strategy. Most businesses that “adopt AI marketing tools” end up with a pile of underused software licenses and no measurable change in output, because nobody thought through integration before signing up for the free trial.

What These Tools Actually Do, Grouped by the Job, Not the Brand Name

Rather than another tool-by-tool rundown, it’s more useful to think in terms of the actual jobs AI marketing tools handle, since that’s the decision that matters before any specific product gets chosen:

  • Content drafting and copy generation — tools like ChatGPT, Claude, and Jasper turn a rough brief into a first draft across blog posts, ad copy, and email. The realistic value here is speed on the first 70% of a draft, not a finished, publish-ready asset.
  • Multi-channel campaign assembly — tools like HubSpot’s Campaign Assistant take one input and generate matching assets across email, social, and landing pages simultaneously, which matters more for consistency than for any single asset’s quality.
  • SEO and content optimization — tools like Surfer SEO analyze what’s already ranking and suggest structural changes, which is genuinely useful but assumes someone is still making the actual editorial judgment calls.
  • AI visibility and brand monitoring — a newer category (Similarweb’s AI Brand Visibility feature is a recent example) that tracks how often a brand gets mentioned inside AI-generated chat responses, not just traditional search results.
  • Marketing automation and workflow orchestration — platforms that connect the other categories together so a lead’s behavior actually triggers the right next action, rather than living in five separate dashboards.

Most businesses only ever adopt tools from the first two categories, because they’re the most visible and the easiest to demo. The last category — actual orchestration — is where the real return sits, and it’s the one most listicles skip entirely because it’s harder to screenshot.

The Real Decision: Point Tools vs. an Integrated Stack

Every business adopting AI marketing tools eventually hits the same fork: keep adding individual point tools as needs arise, or invest in a smaller number of tools that are actually wired together. Both are legitimate, and the right answer depends on scale, not preference.

Point tools make sense when: the team is small, the use case is narrow (one person needs faster first-draft copy), and there’s no one dedicated to managing integrations. This is the right starting point for most businesses under 20 people, and it’s genuinely fine to stay there.

An integrated stack makes sense when: multiple people touch the same campaigns, data needs to flow between tools without manual re-entry, and the business has enough volume that a 10% efficiency gain across the whole funnel is worth more than a faster first draft on any single piece of content. This is where marketing automation platforms genuinely earn their cost — not by writing better copy than ChatGPT, but by making sure the right message reaches the right person at the right moment without someone manually checking five dashboards.

What Every Listicle Gets Wrong: Tool Sprawl Is the Actual Failure Mode

The pattern that shows up repeatedly in real implementations, not in vendor marketing: a business adopts three or four AI marketing tools independently, over a period of months, each solving one immediate problem. Six months later, nobody can say definitively which tool is actually driving results, because none of them talk to each other and the data lives in separate silos. The tools aren’t the problem — the lack of a decision about how they connect is.

This is a genuinely common and avoidable failure. Before adding a third or fourth AI tool to an existing stack, the more valuable question is usually not “which tool is best” but “does this tool need to talk to the tools I already have, and if so, does it actually do that, or will I be manually copying data between them in three months.”

A Practical Starting Framework

Before evaluating any specific product, four questions genuinely change the outcome:

  1. What’s the one bottleneck this needs to solve? Not “we want to use AI” — a specific, named bottleneck (slow first drafts, inconsistent campaign assets, no visibility into AI-search brand mentions).
  2. Who owns it once it’s live? A tool with no clear owner becomes the unused subscription six months later. This should be a named person, not “the marketing team.”
  3. Does it need to connect to anything you already use? If yes, verify the actual integration exists and works before buying — a listed “integration” on a pricing page is not the same as a tested, working connection.
  4. What does success look like in 90 days, specifically? A measurable outcome, not “see how it goes.”

Answering these four honestly before evaluating any specific tool eliminates most of the tool-sprawl problem before it starts.

How to Actually Evaluate a Specific Tool Before Buying

Once the four questions above point toward a genuine need, the actual evaluation of a specific product benefits from a short, consistent checklist rather than a fresh judgment call each time:

  • Ask for the actual output on your own content, not the demo example. Every AI marketing tool demo is tuned to look impressive on a curated sample. Run it on a real, slightly awkward piece of your own brand’s content before deciding anything.
  • Check what happens to your data. Marketing content often includes customer information, pricing details, or unreleased campaign plans. Understand explicitly whether the tool trains on your inputs, and whether that’s acceptable for your specific content.
  • Test the free tier or trial with a real deadline, not a sandbox exercise. Tools behave differently under real time pressure than in a leisurely evaluation — that’s often where genuine gaps between the marketing pitch and daily reality show up.
  • Confirm the integration claim with the tool actually connected, not just listed. “Integrates with HubSpot” on a pricing page and a working, tested connection between your specific accounts are two different things — verify the second before committing budget.

Common Mistakes Worth Naming Directly

Buying the tool before defining the workflow

The most common failure pattern: a business sees a demo, gets excited, buys the tool, and only then tries to figure out how it fits into existing work. The fix is genuinely simple — write down the current workflow first, then look for the specific step an AI tool would improve, rather than starting from the tool.

Treating AI-generated output as finished, not a first draft

Every current AI marketing tool, including the well-known ones, produces output that needs a human editorial pass before it goes out under a real brand’s name. Skipping that step is the single most common cause of AI-generated content reading as generic — not because the tool is bad, but because the editing step got skipped.

Ignoring where AI search visibility fits

Most businesses still measure marketing tool success purely by traditional search and social metrics, missing the newer AI Brand Visibility category entirely — a genuine blind spot given how much research now happens inside AI chat assistants before it ever reaches a traditional search engine.

The Honest Timeline for Seeing Real Value

A realistic expectation matters here, because AI marketing tool vendors routinely imply immediate transformation. In practice, the pattern that shows up across real implementations looks more like this: the first month is mostly setup and workflow adjustment, with output quality often lower than the pre-AI baseline while the team learns what the tool is actually good at. Months two and three typically show the first genuine efficiency gains, once the team has learned which tasks to hand to the tool and which still need a human starting point. Meaningful, measurable time savings usually don’t show up clearly until month three or four — not because the tools are slow, but because the human workflow around them takes that long to actually change.

Any vendor or case study promising a dramatically faster timeline than this is either describing an unusually simple use case, or measuring something narrower than genuine team-wide output. Setting this expectation upfront — with whoever owns the tool internally, per the framework above — avoids the common outcome where a genuinely useful tool gets abandoned in month two because it hasn’t yet delivered results that were never realistic to expect that early.

Where This Fits Alongside a Broader Marketing Automation Strategy

Individual AI marketing tools solve individual problems well. The businesses getting compounding value from this moment aren’t the ones with the most tools — they’re the ones who’ve connected a smaller number of tools into one working system, which is exactly what a genuine marketing automation strategy is built to do. If the four-question framework above surfaces a real integration need rather than just a single-task fix, that’s the point where point tools stop being sufficient on their own.

This also connects directly to how AI integration actually works in practice — the same principles apply just as directly to marketing tools specifically. If the agency side of this decision is also on the table, choosing an AI marketing agency runs into the exact same evaluation problem: too many self-promotional rankings, not enough vendor-neutral criteria.

What “Good” Actually Looks Like Six Months In

The businesses that get this right share a specific, recognizable pattern. There are usually two to four AI marketing tools in active use, not eight or ten — each one tied to a specific bottleneck someone identified before buying, not adopted because a competitor mentioned it. Someone can name, without checking a spreadsheet, exactly which tool handles which job and who owns it. When a tool stops earning its subscription cost, it gets cancelled rather than quietly forgotten, because someone is actually accountable for it. And critically, the tools that need to share data actually do, tested and confirmed, not just claimed on a pricing page.

None of this requires picking the single best tool from any list. It requires treating tool adoption as a decision with an owner and a measurable outcome, rather than a purchase made because a demo looked impressive. That discipline, more than any specific product choice, is what separates businesses seeing genuine efficiency gains from AI marketing tools six months in from the ones still paying for licenses nobody opens.

Point Tools vs. Integrated Stack: A Quick Comparison

Factor Point Tools Integrated Stack
Team size Under 20 people 20+ people, multiple hands on the same campaigns
Setup effort Low — sign up and start using Higher — requires actual integration work upfront
Data flow Manual, tool-to-tool Automated, shared across the stack
Best for One narrow, specific bottleneck Coordinated, multi-channel campaigns at volume
Ongoing management Minimal — mostly self-serve Needs a named owner tracking the whole system
Risk if unmanaged One underused subscription Multiple disconnected tools and siloed data

Most businesses starting out should default to the left column and only move right once the specific triggers described earlier — multiple people, real data-sharing needs, meaningful volume — actually show up.

Worth noting too: if the bottleneck your team is actually facing looks more like disorganized social content than disorganized marketing copy generally, choosing a social media management tool is a narrower, related version of this exact same evaluation problem — different tools, same underlying discipline.

Key Takeaways

  • By mid-2026 most marketing teams already use five or more AI marketing tools without a coordinated strategy connecting them — tool sprawl, not lack of tools, is the actual failure mode.
  • Before evaluating any specific product, four questions matter more than any feature list: what specific bottleneck this solves, who owns it once it’s live, whether it actually needs to connect to existing tools, and what success looks like in 90 days.
  • Real value takes longer than vendors imply — month one is mostly setup, months two and three bring the first genuine efficiency gains, and measurable time savings typically don’t show up until month three or four.
  • Point tools (under 20 people, one narrow bottleneck) and an integrated stack (multiple people, shared data, real volume) solve different problems — the right choice depends on scale, not preference.